🚀 Modern Approach — Tokenization
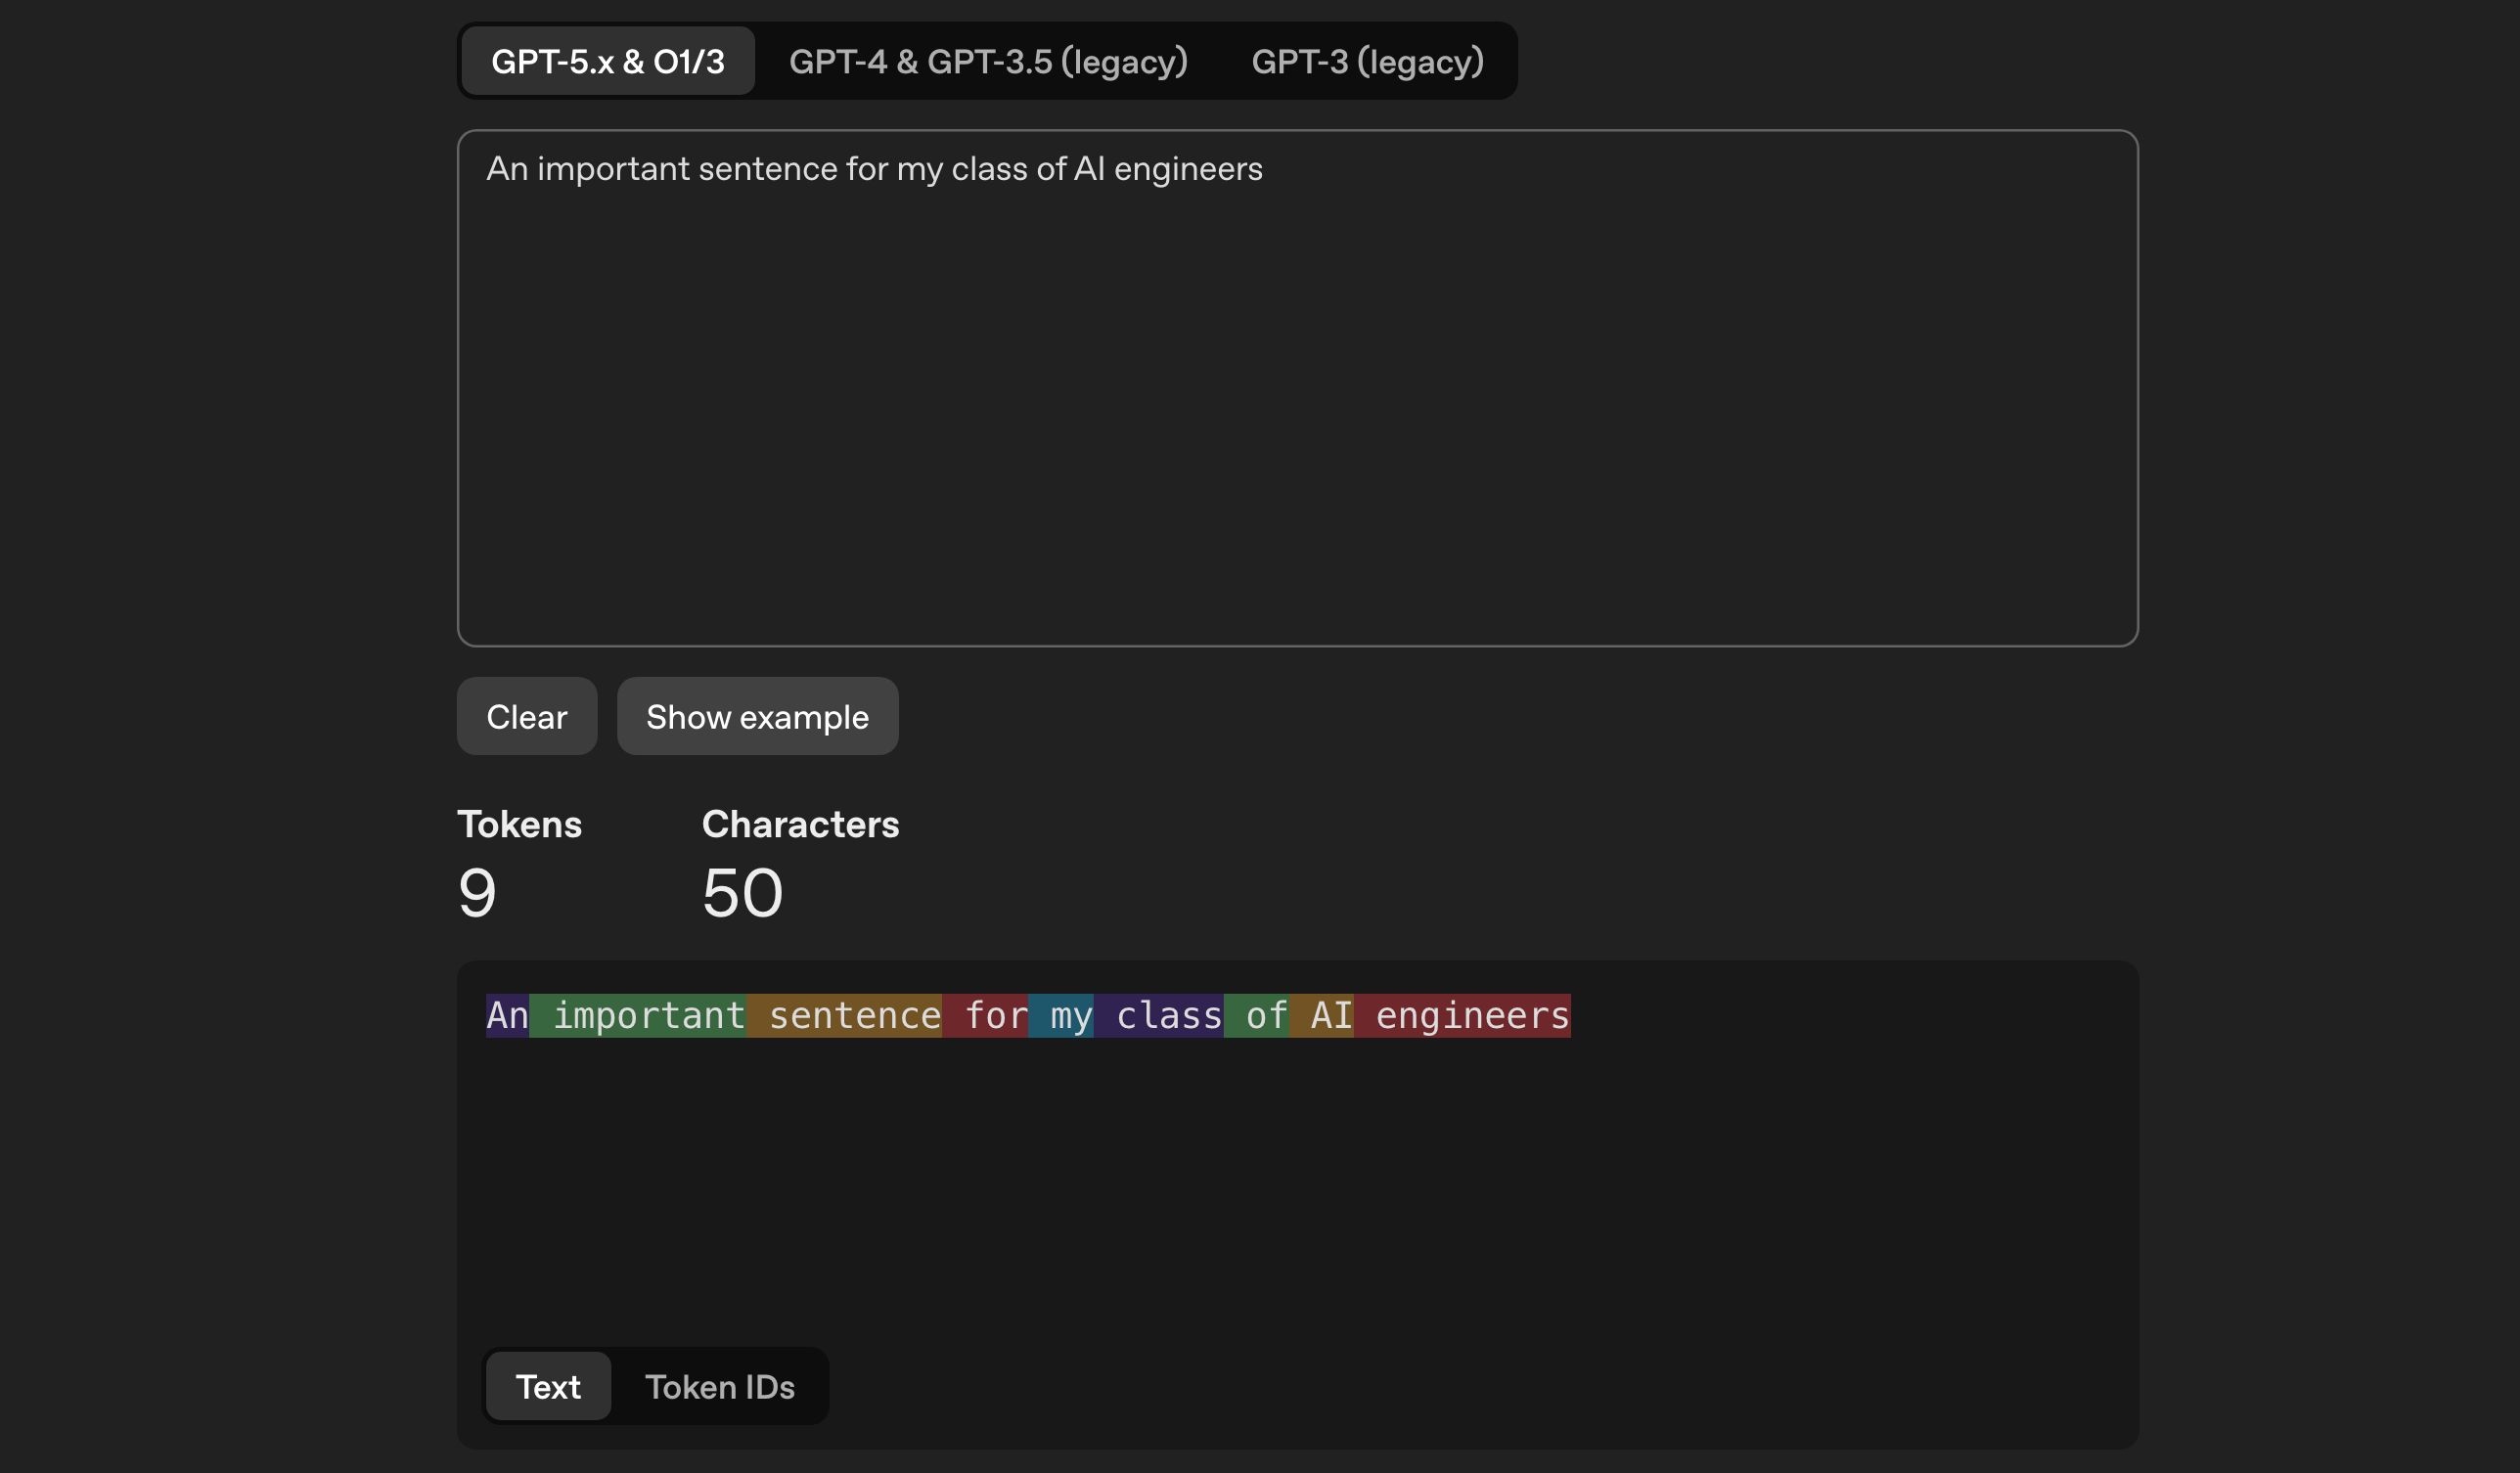
🎨 Spaces Are Part of the Token Too!
Here's something surprising — tokens don't just capture the word itself, they often include the space before it as well! 🤯
" important" — notice the space at the front 👈
This tells the model two things at once:
📍 A new word is starting here
💬 That word is "important"
🧩 Where a Token Appears Matters
The same word can be tokenized differently depending on where it sits:
Type | Example |
|---|---|
🟢 Start of a word |
|
🔵 Fragment inside a word |
|
🔍 Take "unimportant" for example:
→un+important(fragment)
💡 Why This is Clever
By tracking spaces and positions, the model can understand word structure more naturally — recognizing roots, prefixes, and how words connect to each other. 🧠
🔍 Rare Words Get Broken Into Pieces
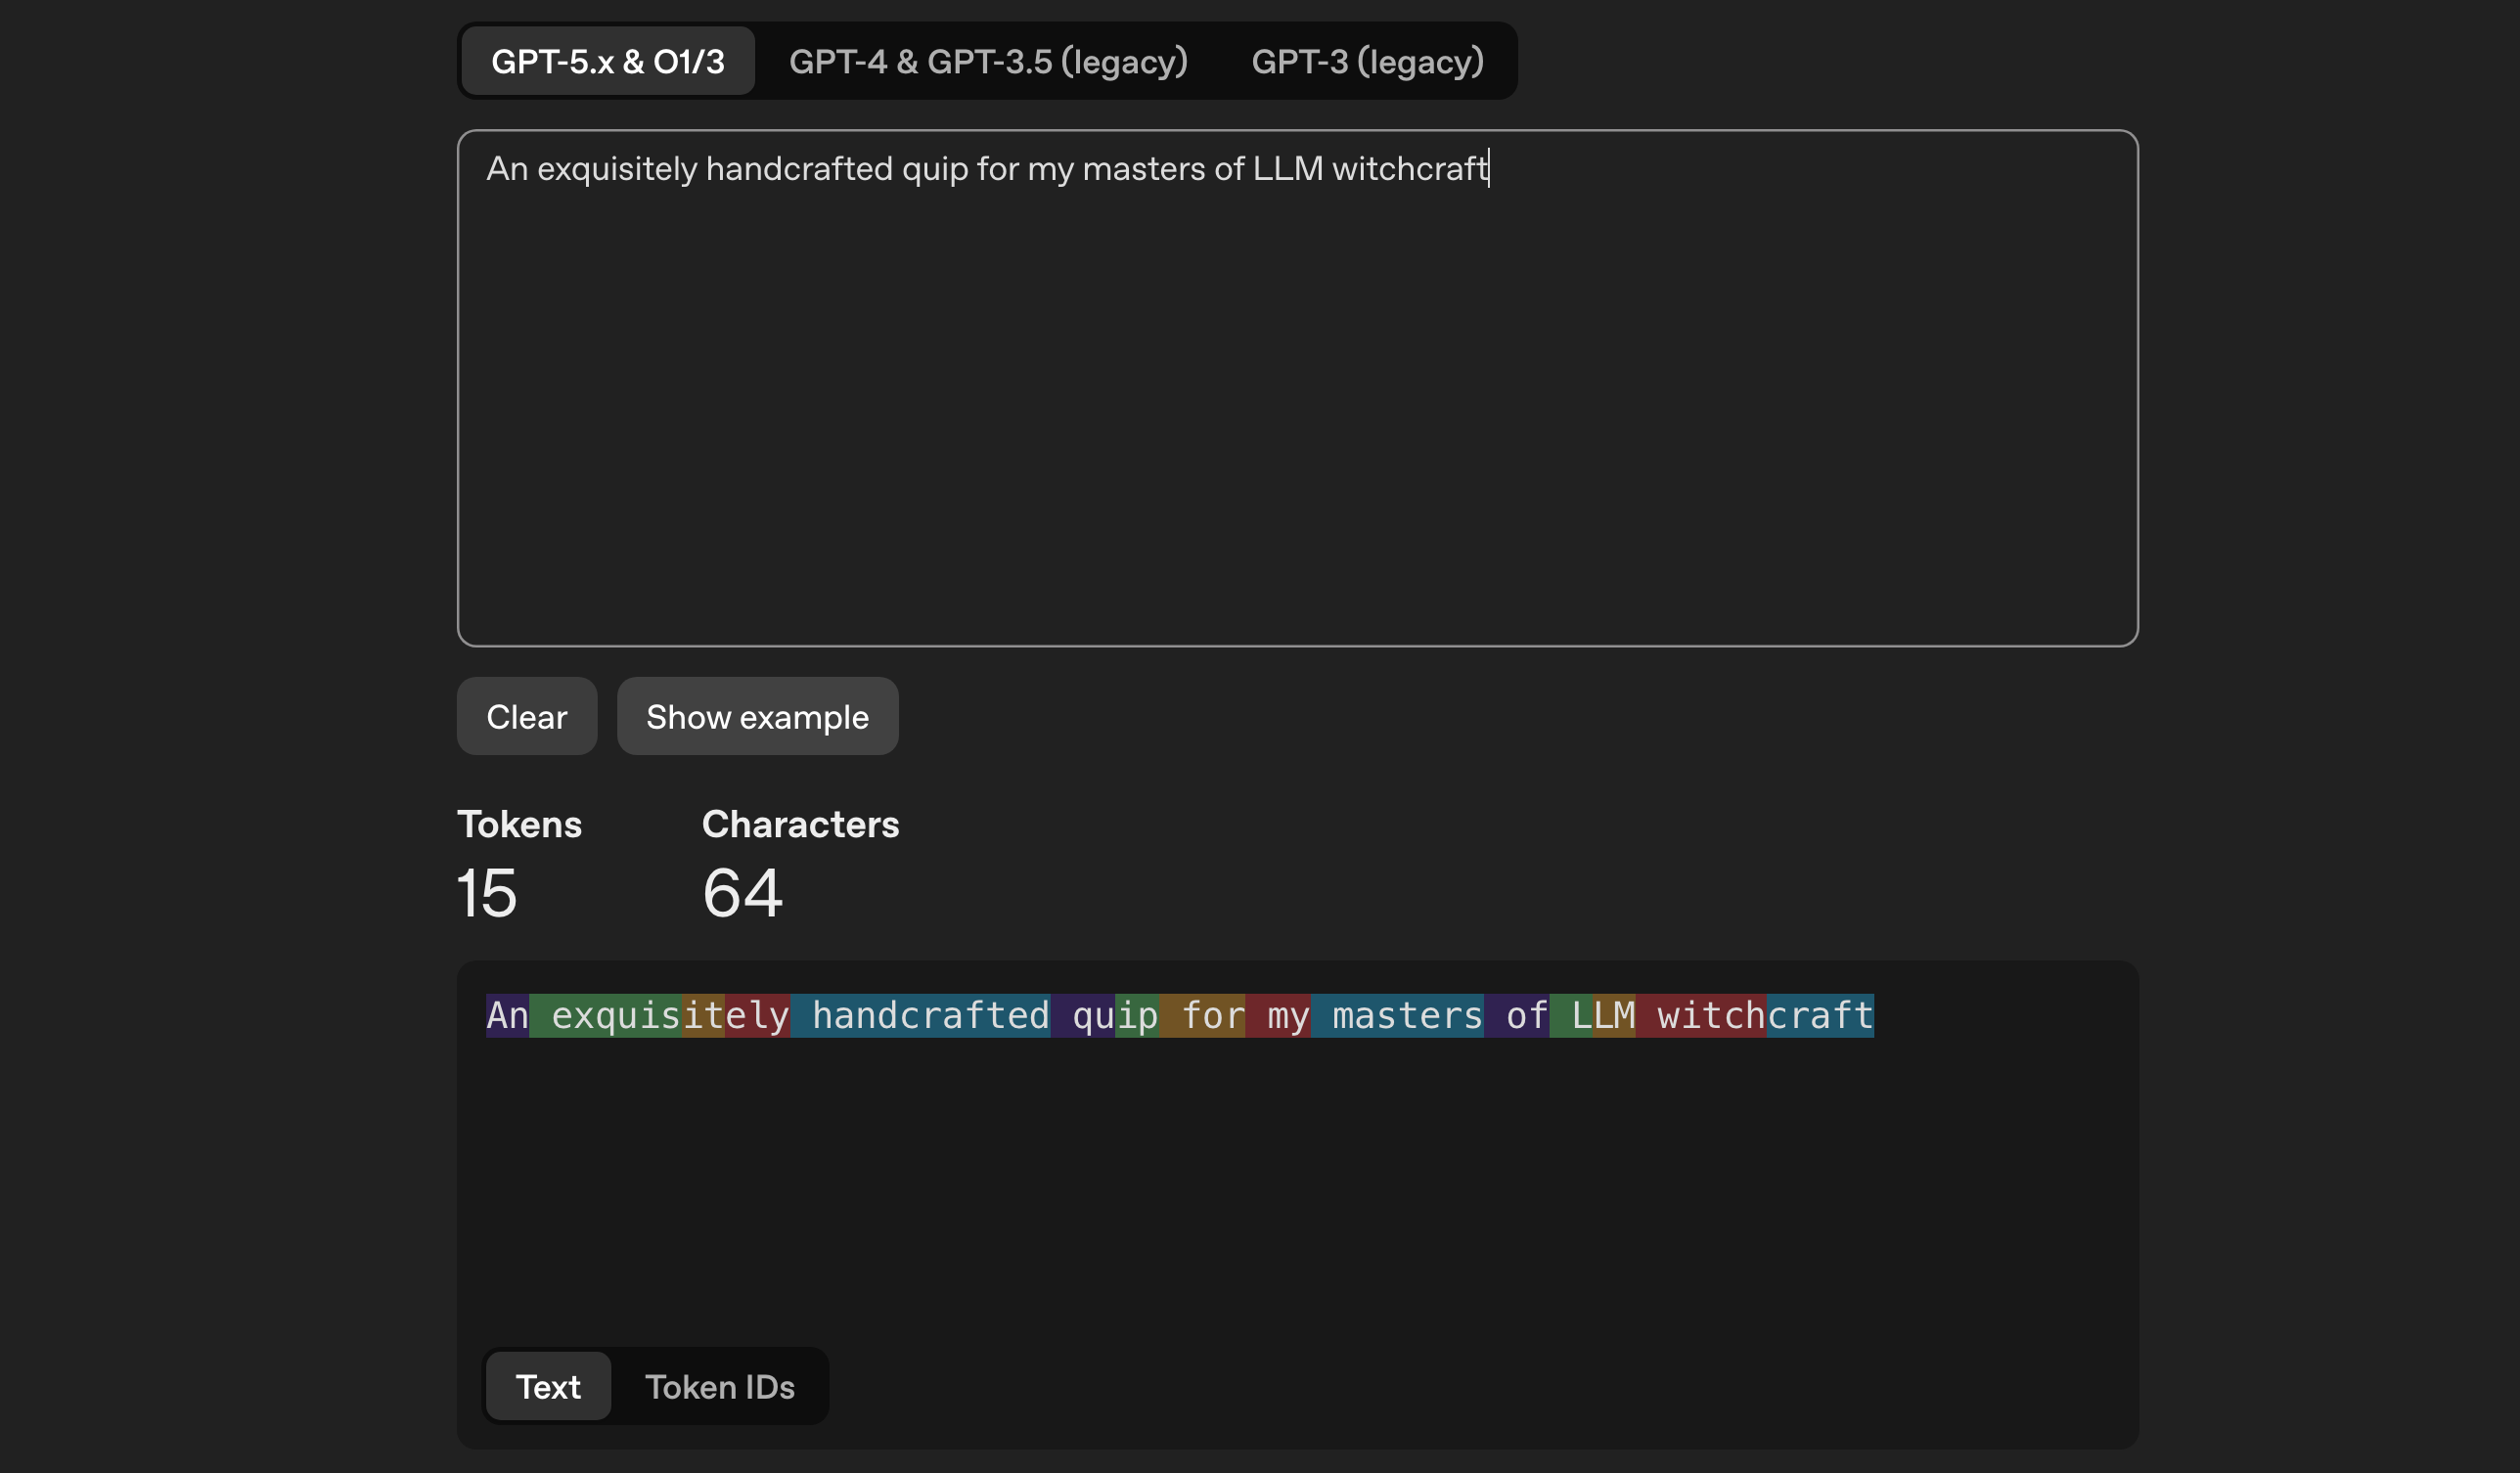
Uncommon words don't get their own token — instead, they're split into smaller, familiar fragments the model already knows. 🧩
🔬 "exquisitely" →
ex+quis+ite+ly
🧠 Why This is Smart
Rather than learning every rare word from scratch, the model reuses its knowledge of:
🔓 Prefixes
🔚 Suffixes
🔗 Common fragments
This leads to faster learning ⚡, sharper pattern recognition 🎯, and a leaner vocabulary 📦.
🧱 Real Word Examples
Word | Token Split |
|---|---|
🤲 handcrafted |
|
🧙 witchcraft |
|
🏆 masters |
|
💡 Worth Noting
Fragment tokens like crafted typically don't carry a leading space — a subtle signal that they're the middle or end of a word, not the start of a new one.
🔢 Numbers Are Also Tokenized
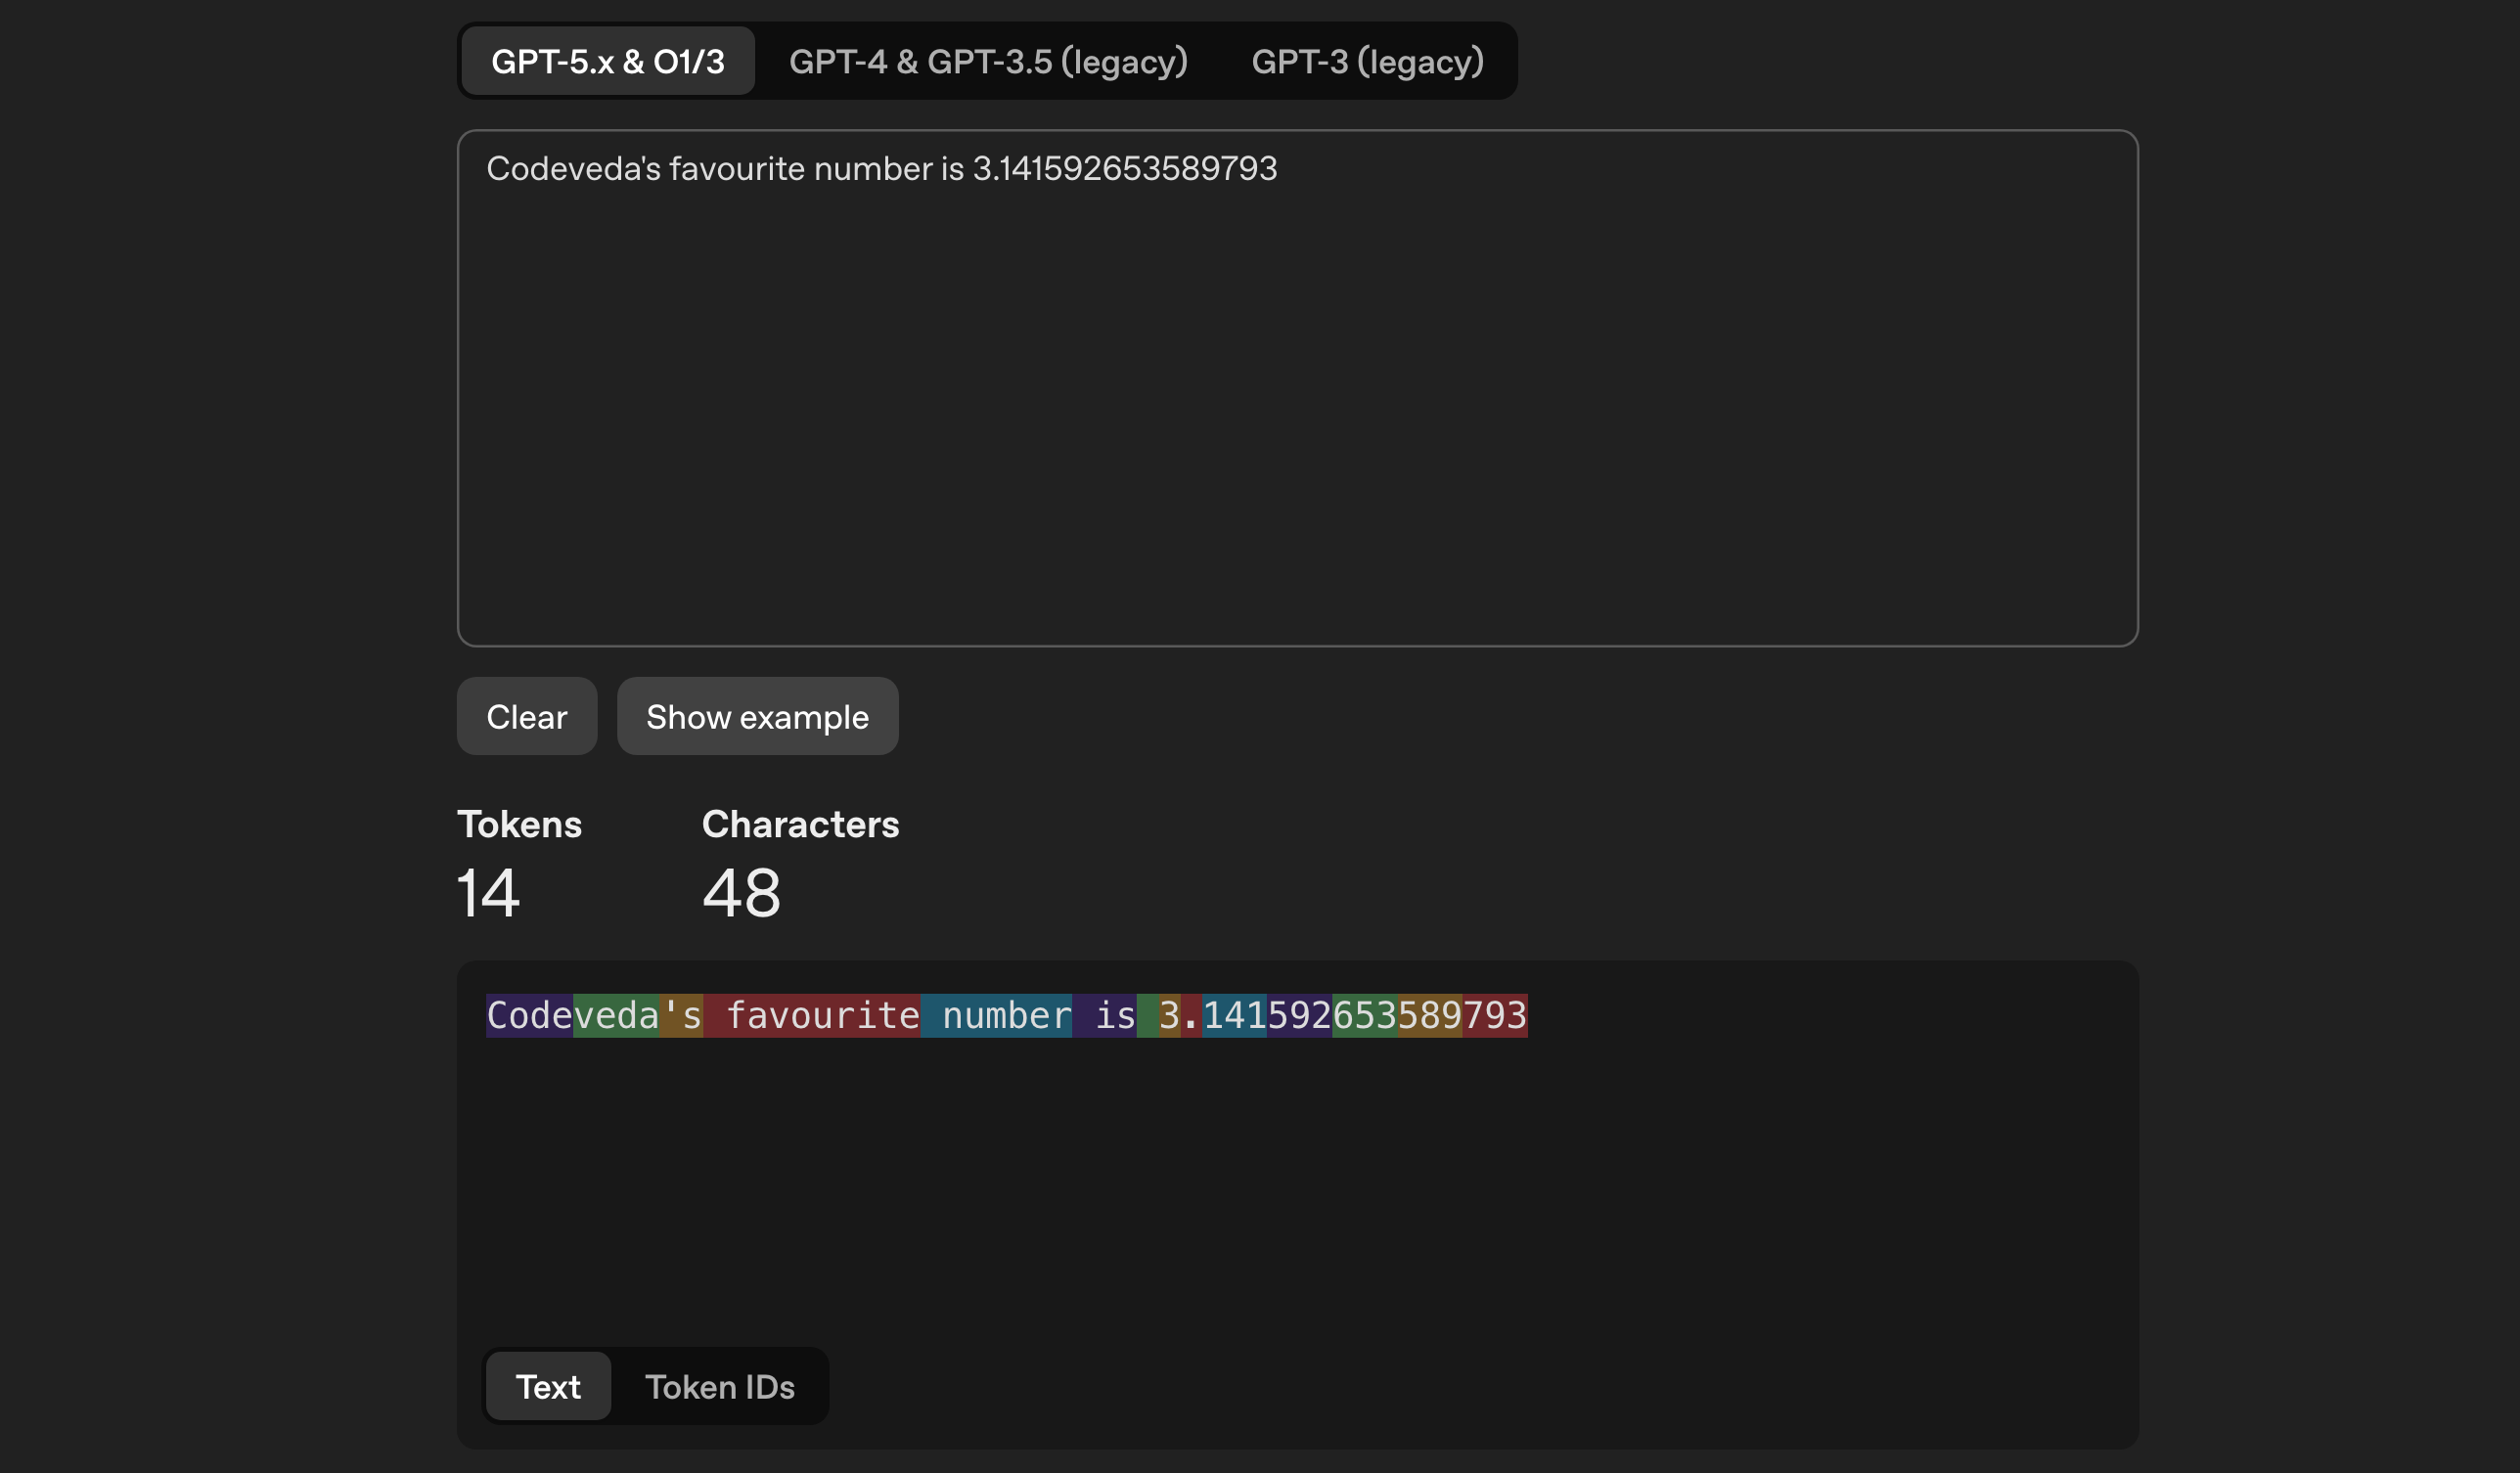
Numbers aren't special — they get chunked just like words!
🔬 3.141592653589793 →
3.+141+592+653+589+793
💡 Fun fact: GPT vocabularies include tokens for every number from 000 to 999 — meaning any 3-digit number is just one single token. 🎯
🤖 Why Old GPT Models Struggled at Math
Problem Type | Difficulty |
|---|---|
🟢 3-digit math | Easier |
🔴 4-digit math | Harder |
Larger numbers split across multiple tokens, making relationships harder to learn. Modern models handle this much better. ✅
📏 Token-to-Word Ratio
A handy rule of thumb:
🔤 1 token ≈ 4 characters or 0.75 words
Tokens | Approx Words |
|---|---|
1,000 | ~750 words |
1,000,000 | ~750,000 words |
📚 The Complete Works of Shakespeare (~900,000 words) is roughly 1.2 million tokens — a popular benchmark for understanding token scale.
💰 Tokens Have a Real Cost
AI APIs charge based on input and output tokens. Understanding tokens helps you:
💵 Estimate API costs
📐 Manage context window usage
🚧 Stay within model limits
⚠️ Code Uses More Tokens
Programming and technical content is token-heavy due to:
🔡 Uncommon variable names
🔣 Dense symbols and syntax
📦 Compressed expressions
const userAuthenticationHandler = ...can split into many fragments 😬
🧪 Try It Yourself!
Play around with tokenizer tools to:
✂️ See how text splits
🔄 Compare different models
🧮 Estimate token counts
This builds real intuition for prompt engineering 🛠️, cost optimization 💰, and context management 🧠.