🧠 What is a Context Window?
Think of the context window as the model's working memory — it's the maximum amount of text the LLM can see and process at any one time. 👁️
📦 What Fits Inside It?
Everything gets counted toward the limit:
💬 Your current message
📜 The full conversation history
🤖 The model's previous replies
✍️ Tokens being generated in the current response
⚠️ What Happens When It's Full?
Once the total tokens exceed the limit, the model simply cannot process any further — it's like trying to pour water into an already full glass. 🥛
💡 The Simple Way to Think About It
Just like humans can only hold so much information in their head at once, an LLM can only "see" a limited chunk of the conversation at any given moment. 🧩
🔄 How LLMs Generate Responses
LLMs don't write responses all at once — they build them one token at a time, like constructing a sentence brick by brick. 🧱
📖 Example: Watch It Unfold
👤 User asks: "What is my name?"
Step | What the model sees |
|---|---|
1️⃣ |
|
2️⃣ |
|
3️⃣ |
|
4️⃣ | ...and so on until the response is complete ✅ |
Each new token gets added to the sequence, which then feeds back in to predict the next one.
⚠️ Why Context Window Size Matters
A bigger context window means the model can:
🗣️ Remember longer conversations
🔍 Reference details mentioned much earlier
📄 Handle large documents with ease
🧠 Perform deeper, more accurate reasoning
🛠️ Support advanced prompting techniques
💡 The bigger the window, the more the model can "hold in its head" at once!
🧨 Important Use Cases
Multi-shot prompting
Giving several examples before the actual task
RAG (Retrieval-Augmented Generation)
Injecting external knowledge into prompts
Agent systems
Long-running workflows and memory chains
💰 How API Pricing Actually Works
Chat products like OpenAI and Anthropic offer free and paid plans — but APIs are different. With APIs, you pay for exactly what you use, based on token consumption. 🧮
🧾 What You're Actually Paying For
1️⃣ Input Tokens — Everything you send to the model:
📜 Full conversation history
⚙️ System prompts
🧠 Memory & RAG data
💬 Current user message
2️⃣ Output Tokens — Everything the model generates:
✍️ The visible response text
🔍 Hidden reasoning traces (in reasoning models)
⚠️ Even if the reasoning is invisible to you, the computation still happens — and you still get billed for it!
📈 Costs Grow With Conversation Length
The longer a conversation gets, the more tokens get reprocessed with every single message. This is simply how transformers work — they look back at all prior tokens every time. 🔄
🧠 Reasoning Models Can Get Pricey
Reasoning models think deeply before responding — generating large internal reasoning traces behind the scenes. You pay for:
✅ The answer you see
💸 The reasoning you don't
💡 Always factor in hidden reasoning costs when budgeting for reasoning models!
⚡ Prompt Caching — A handy Cost Saver!
Some API providers offer prompt caching — a smart optimization that kicks in when the same input is sent repeatedly.
Instead of recomputing everything from scratch, the provider reuses previous computations, making repeated inputs significantly cheaper 💰 and faster ⚡.
✅ Best part? In some systems this happens completely automatically — no extra setup needed! 🙌
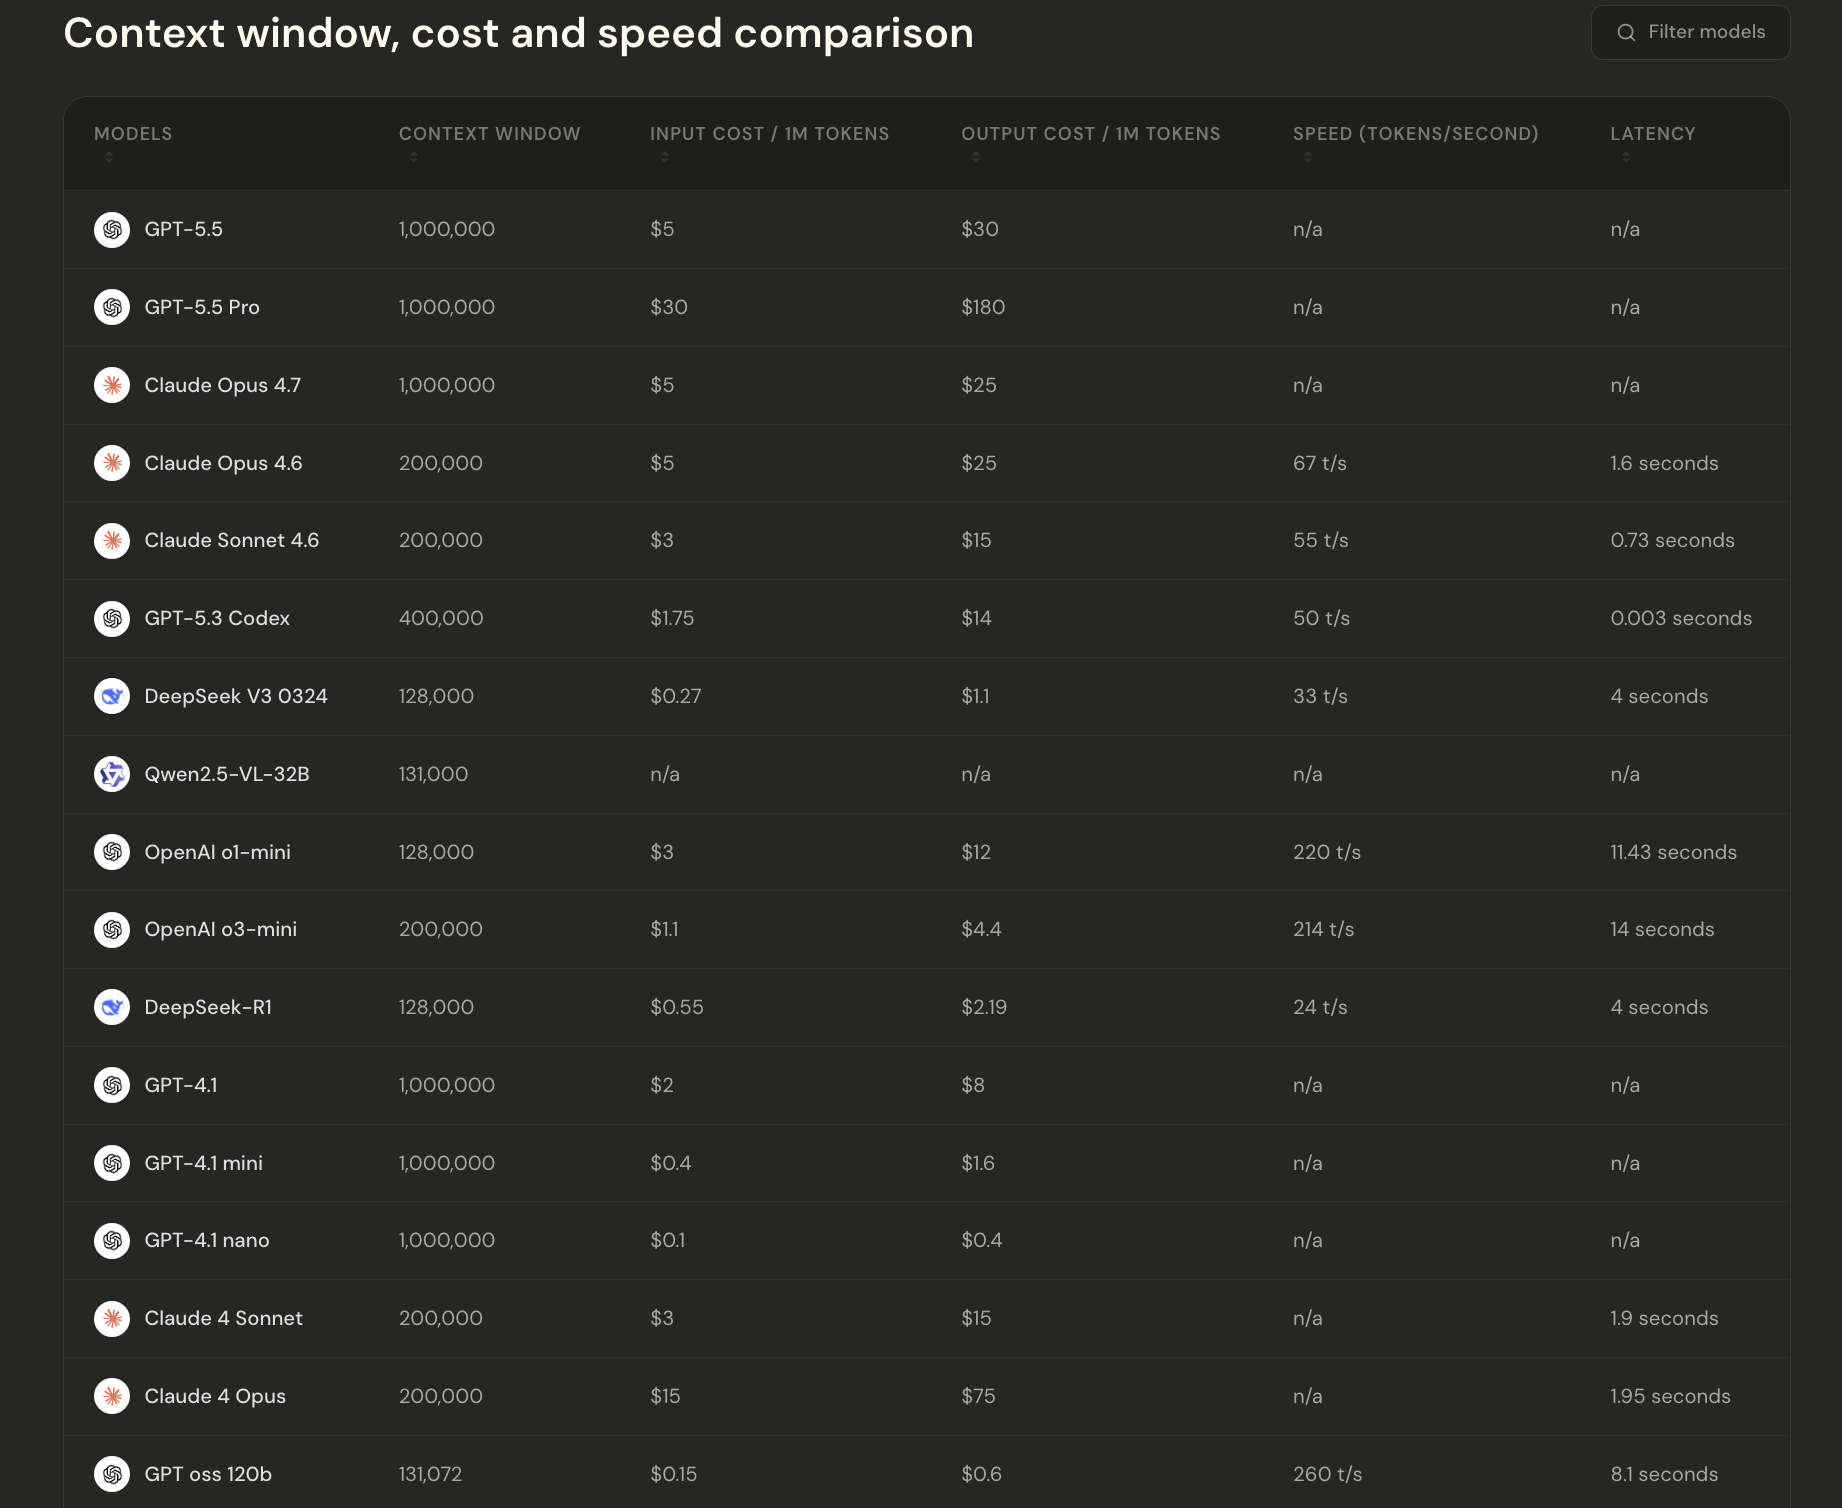
📊 Context Window, Pricing, Speed & More — Model Comparison
👉 https://www.vellum.ai/llm-leaderboard
✅ Special Note
Understanding which model to use — based on context window, pricing, and speed — is an essential skill for any great AI engineer. Every use case is unique and demands a different solution.