🧠 What is Prompt Caching?
When you send a large input context (e.g. a long document, system prompt, or reference text) to an LLM, the provider processes all those tokens every time — which costs money and takes time.
Prompt caching lets providers reuse the processed version of that input if they see it again soon, so you pay less and get faster responses.
💡 Think of it like a browser cache — instead of re-downloading the same page, it serves it from memory.
🔬 LiteLLM Demo — Seeing Caching in Action
( Level2 → part1.ipynb )
Import LiteLLM in Case you haven’t
▶️ Create a new code cell and run it:
from litellm import completionLoad the context (Hamlet.txt)
download from below link:
https://github.com/codevedadev/ai-engineering-core/blob/main/level2/hamlet.txt
▶️ Create a new code cell and run it:
with open("hamlet.txt", "r", encoding="utf-8") as f:
    hamlet = f.read()

loc = hamlet.find("Speak, man")
print(hamlet[loc:loc+100])
# sanity check a snippet
Ask without context (hallucination test)
▶️ Create a new code cell and run it:
question = [{"role": "user", "content": "In Hamlet, when Laertes asks 'Where is my father?' what is the reply?"}]

response = completion(model="gemini/gemini-2.5-flash-lite", messages=question)
display(Markdown(response.choices[0].message.content))
❌ Model hallucinated a confident but wrong answer
Because no context attached = no accuracy
▶️ Create a new code cell and run it:
print(f"Input tokens:  {response.usage.prompt_tokens}")
print(f"Output tokens: {response.usage.completion_tokens}")
print(f"Total tokens:  {response.usage.total_tokens}")
print(f"Total cost:    {response._hidden_params['response_cost']*100:.4f} cents")
Inject full Hamlet as context
▶️ Create a new code cell and run it:
question[0]["content"] += "\n\nFor context, here is the entire text of Hamlet:\n\n" + hamletFirst call WITH context
▶️ Create a new code cell and run it:
response = completion(model="gemini/gemini-2.5-flash-lite", messages=question)
display(Markdown(response.choices[0].message.content))
✅ Correct answer because context attached: "Dead."
▶️ Create a new code cell and run it:
print(f"Input tokens:  {response.usage.prompt_tokens}")
print(f"Output tokens: {response.usage.completion_tokens}")
print(f"Cached tokens: {response.usage.prompt_tokens_details.cached_tokens}")
print(f"Total cost:    {response._hidden_params['response_cost']*100:.4f} cents")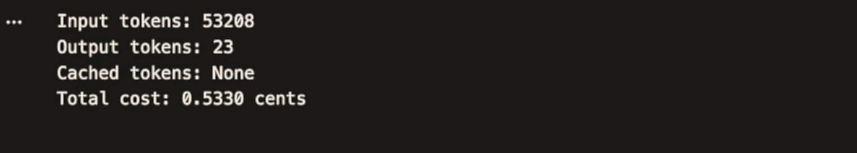
Second identical call (cache kicks in)
▶️ Create a new code cell and run it:
response = completion(model="gemini/gemini-2.5-flash-lite", messages=question)
▶️ Create a new code cell and run it:
print(f"Input tokens:  {response.usage.prompt_tokens}")
print(f"Output tokens: {response.usage.completion_tokens}")
print(f"Cached tokens: {response.usage.prompt_tokens_details.cached_tokens}")
print(f"Total cost:    {response._hidden_params['response_cost']*100:.4f} cents")
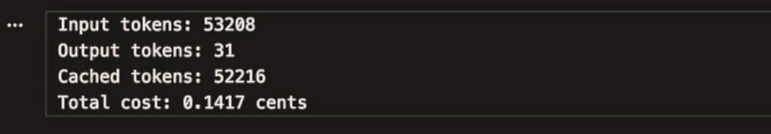
💰 ~5× cheaper on the second call — automatically, no code changes needed
📊 Token Cost Summary
Call | Input Tokens | Cached Tokens | Cost |
|---|---|---|---|
No context | ~19 | 0 | ~0.004¢ |
With context (1st) | ~53K | 0 | ~0.5¢ |
With context (2nd) | ~53K | ~44K | ~0.1¢ |
🔑 The Golden Rule of Prompt Caching
⚠️ Static content first, dynamic content last.
For caching to work, the beginning of your prompt must match between calls. As soon as the prefix differs, there's a cache miss.
✅ CORRECT:  [Full Hamlet text]  →  [Question about Hamlet]
❌ WRONG:    [Question]          →  [Full Hamlet text]
If you put today's date or the user's question at the top, every call will be a cache miss because the prefix changes every time.
🔵 OpenAI Prompt Caching
✅ Fully automatic — no code changes needed
🔍 Only works on exact prefix matches — the beginning of the prompt must be identical
💰 Cached input tokens cost 4× less
🖼️ Applies to images and tools too — they must also be identical between requests
🟠 Anthropic Prompt Caching
⚙️ Manual — you must explicitly tell Anthropic what to cache ("priming")
💸 Priming the cache costs 25% more upfront
💰 But reusing from cache costs 10× less — a much bigger saving than OpenAI
🧮 Best for large, stable system prompts or documents used repeatedly
Trade-off summary:
OpenAI | Anthropic | |
|---|---|---|
Setup | Automatic | Manual (explicit) |
Cache prime cost | None | +25% |
Cache hit saving | 4× cheaper | 10× cheaper |
🟢 Gemini Prompt Caching — Implicit vs Explicit
📎 Docs
Gemini supports both modes:
🔇 Implicit Caching (automatic)
Works like OpenAI — Gemini detects repeated prefixes and caches them automatically
No code changes required
What happened in the demo above — Gemini cached Hamlet on the second call without any setup
🔊 Explicit Caching (manual)
You proactively create a named cache object with the content you want stored
Gives you more control — you can set a TTL (time-to-live), reuse across many sessions, and confirm it's cached before paying for calls
Similar philosophy to Anthropic's approach but with Gemini's API
When to use which:
Implicit | Explicit | |
|---|---|---|
Setup effort | None | Requires extra API calls |
Best for | Short sessions, quick experiments | Long-running apps, production systems |
Control | Low | High |